

TLDR
- An adviser to the EU’s top court said AI chatbots can infringe copyright when they reuse press articles.
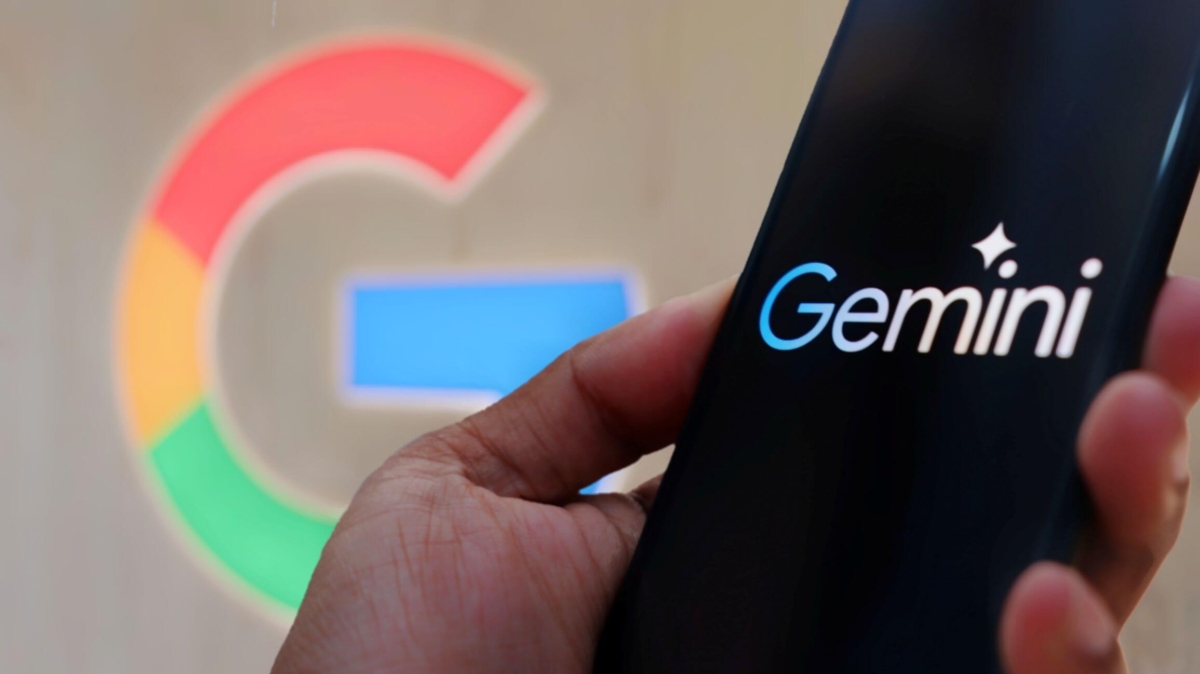
- The case involves Hungarian publisher Like Company and Google’s Gemini chatbot.
- Copyright does not cover mere facts, only the specific form of expression.
- Using copyrighted material to train AI models is freely permitted under EU rules, the adviser said.
- The opinion is not binding, and Hungarian judges will issue a verdict later.
An adviser to the European Union’s highest court said Google’s use of news stories in its Gemini chatbot can infringe copyright rules in some cases. Advocate General Maciej Szpunar gave the opinion on Tuesday. He advises the Court of Justice of the European Union, based in Luxembourg.
The case was brought by Hungarian digital publisher Like Company against Google’s artificial intelligence chatbot. Judges in Hungary asked the Luxembourg court for guidance on the matter.
What the Adviser Said
Szpunar said a press publisher’s right may be infringed in certain circumstances. This can happen when a chatbot retrieves a publication from a publisher’s website. It applies if the chatbot then reuses that publication to generate an answer for a user.
He pointed to two situations where Gemini’s answers fall under the publisher’s right of reproduction. The first is when a chatbot gets access to articles by getting around paywalls or other technical barriers. The second is when it reuses the form of expression of a publication in a recognisable manner.
The court said the press publisher’s right does not protect the mere facts reported in articles. It protects only the specific form of expression used in them. Szpunar said courts should look at whether an answer only reports facts from an article.
He also said they should check whether the answer reuses the publication’s wording to such an extent that the user is entirely dispensed from accessing the original publication. In that case, the reader would have no need to visit the publisher’s site.
Like Company argued that Google used copyrighted articles to train large language models. It also said Google repeatedly reproduced them through Gemini between June 2023 and May 2024.
Szpunar said there is no evidence that Like Company’s articles were used to train Gemini’s models. He added that models can be trained using copyrighted material under EU law. He said such use is freely permitted under the text and data mining exception.
Large language models are AI systems that use vast amounts of text to generate human-like responses and summarize information. Publishers have seen web traffic fall as AI-written news summaries replace traditional search results that include links.
A ruling against Google could force the company to pay fees for the use of publisher content. Google did not immediately respond to a request for comment.
News Corp, the owner of The Wall Street Journal, has a commercial agreement to supply content on Google platforms.
The advocate general’s opinion is not binding on the court. The court’s judges usually follow such opinions. It is now up to judges in Hungary to issue a verdict at a later date.
